Train and post-train on managed GPUs
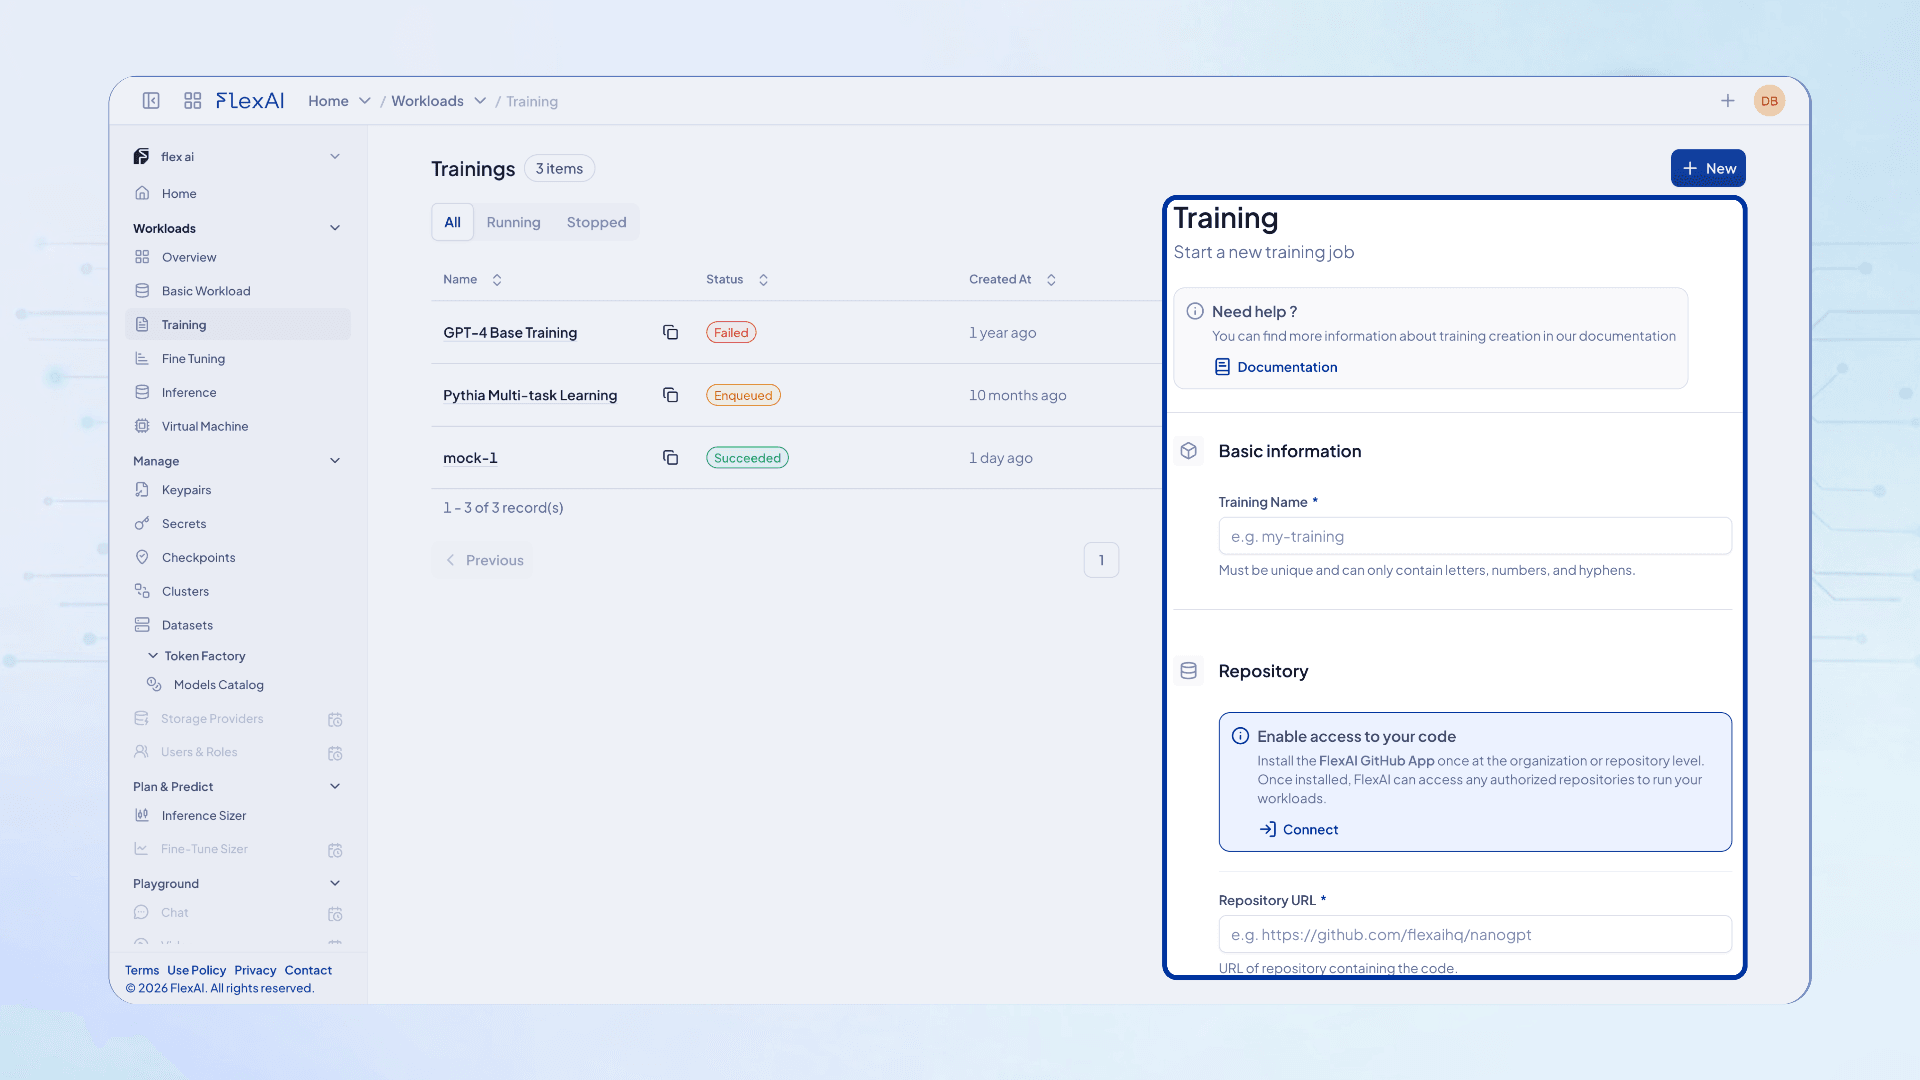
Bring your datasets and code. FlexAI handles orchestration, checkpoints and workload placement.
Train and post-train the models that power your agents, then deploy winners back into Token Factory, Dedicated GPUs, or AgentOS workflows.
Pre-training and post-training
Large Scale Support
- 1 to 1000s of GPUs
- Multi-node distributed
- Multi-region compute
Performance & Resilience
- Parallelized execution
- Auto checkpointing
- Managed data pipelines
Built-in Observability
- TensorBoard · Visualize metrics and graphs
- Weights & Biases · Track experiments at scale
- Grafana · Infrastructure monitoring
One interface for every run
For end users and admins, with governance and visibility built in.
What customers say
"Compared to other platforms I have used, FlexAI provides a more cost effective and hassle free experience for training and deploying my models.
LegML
"FlexAI enabled us to prove the value of our model in record time and make it to Y Combinator.
Dollyglot.com
"The ability to manage compute resources across multiple cloud providers through a unified interface is a game changer.
Pixelcut
Sizing a training run? Use the GPU savings calculator to compare H100/H200 costs against hyperscalers, or work out when serverless stops paying off. Need dedicated capacity for the largest jobs? See Dedicated GPUs.
- 1Pick a blueprint for your model family and stage
- 2Set constraints: budget, speed, region, reliability
- 3Launch. Observe. Promote the winner
Frequently Asked Questions
What you can train on
The same supported matrix as the rest of the platform, so a training run and the endpoint that serves its output sit on the same substrate.
- Accelerators
- NVIDIAAMD
- Architectures
- CUDAROCm
- Precisions
- FP8NVFP4MXFP4BF16FP16FP32
- Inference engines
- vLLMSGLangTritonCustom
- Fine Tuning & Training
- PyTorchAxolotlLlamaFactoryTRLDeepSpeed
- Observability & Tools
- GrafanaPrometheusTensorBoardWeights & Biases
More managed AI services: inference, fine-tuning, and the platform overview.